P-H3-Image · 8-Step
Pruna AI's 8-step CFG-free 8MP open-weight checkpoint built on the MiniMax-H3 backbone for photorealistic stills, quoted poster typography and reference edits.
Inputs and settings
- Aspect ratio
- 1:116:99:164:33:43:22:3
- Output size
- 1K / 2K / 4K
- Reference
- Up to 4 images
Examples
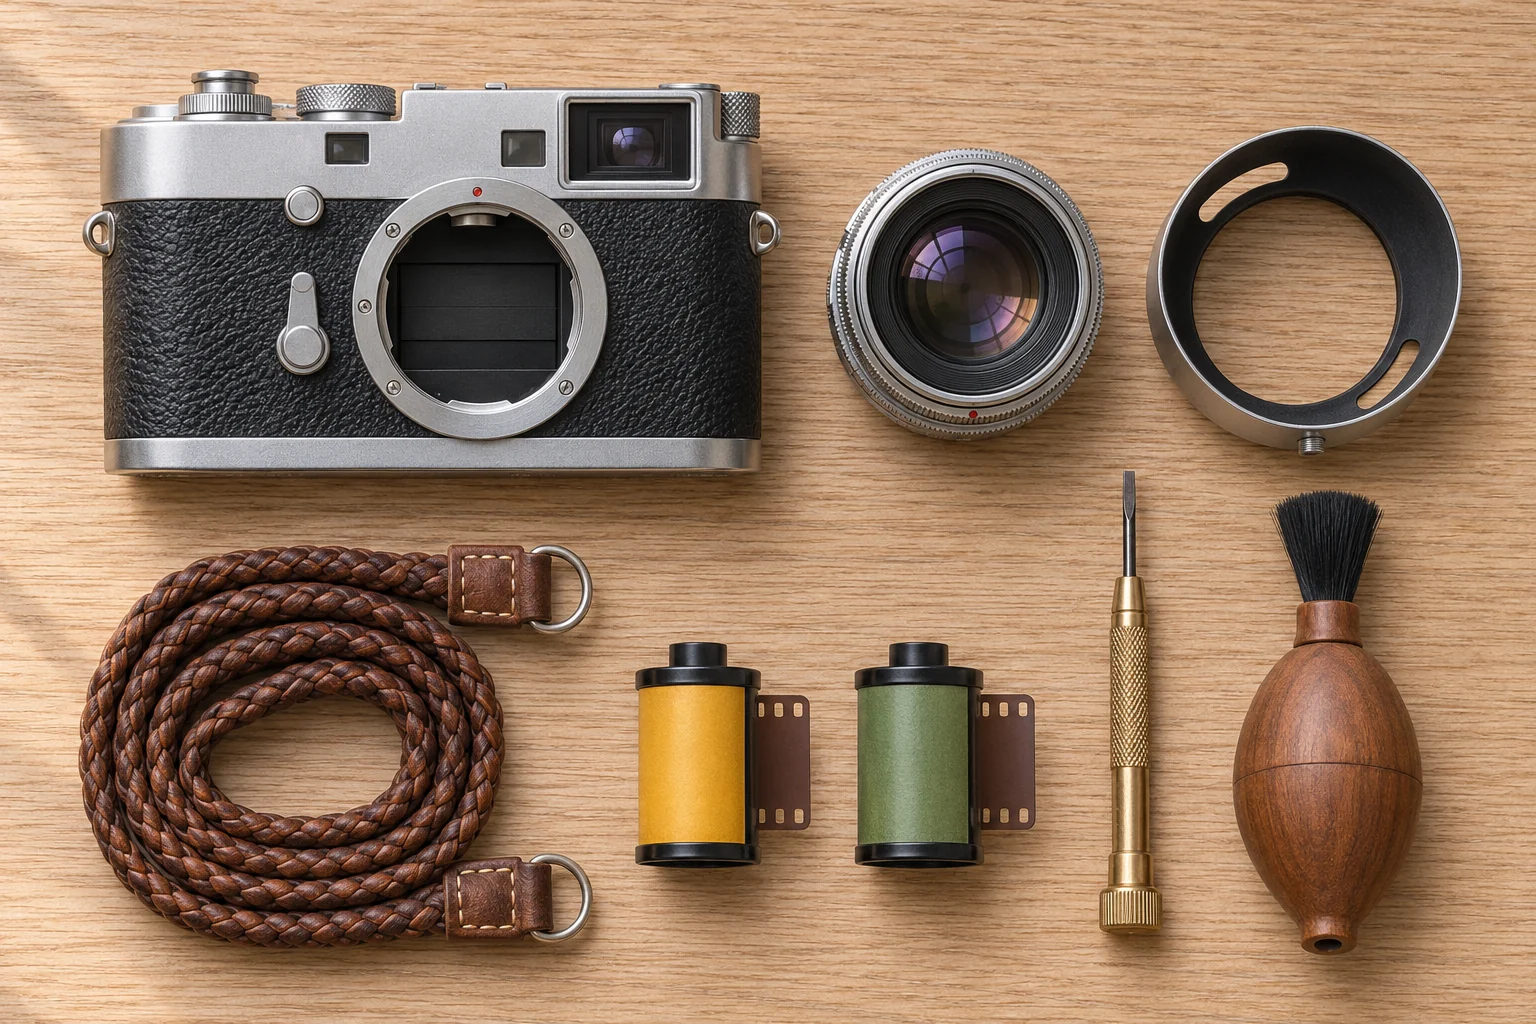
Knolling 35mm Rangefinder Flat-Lay
A knolling photograph shot from directly above: a vintage silver and black 35mm rangefinder film camera taken apart into its camera body, 50mm prime lens, metal lens hood, braided leather strap, two 35mm film rolls, a brass precision screwdriver, and a wooden blower brush, all laid out at strict right angles with even gaps on a pale oak table. Soft daylight from the left, sharp edge-to-edge focus, no text.
Source · MiniMax H3 Community License · 2026-11-03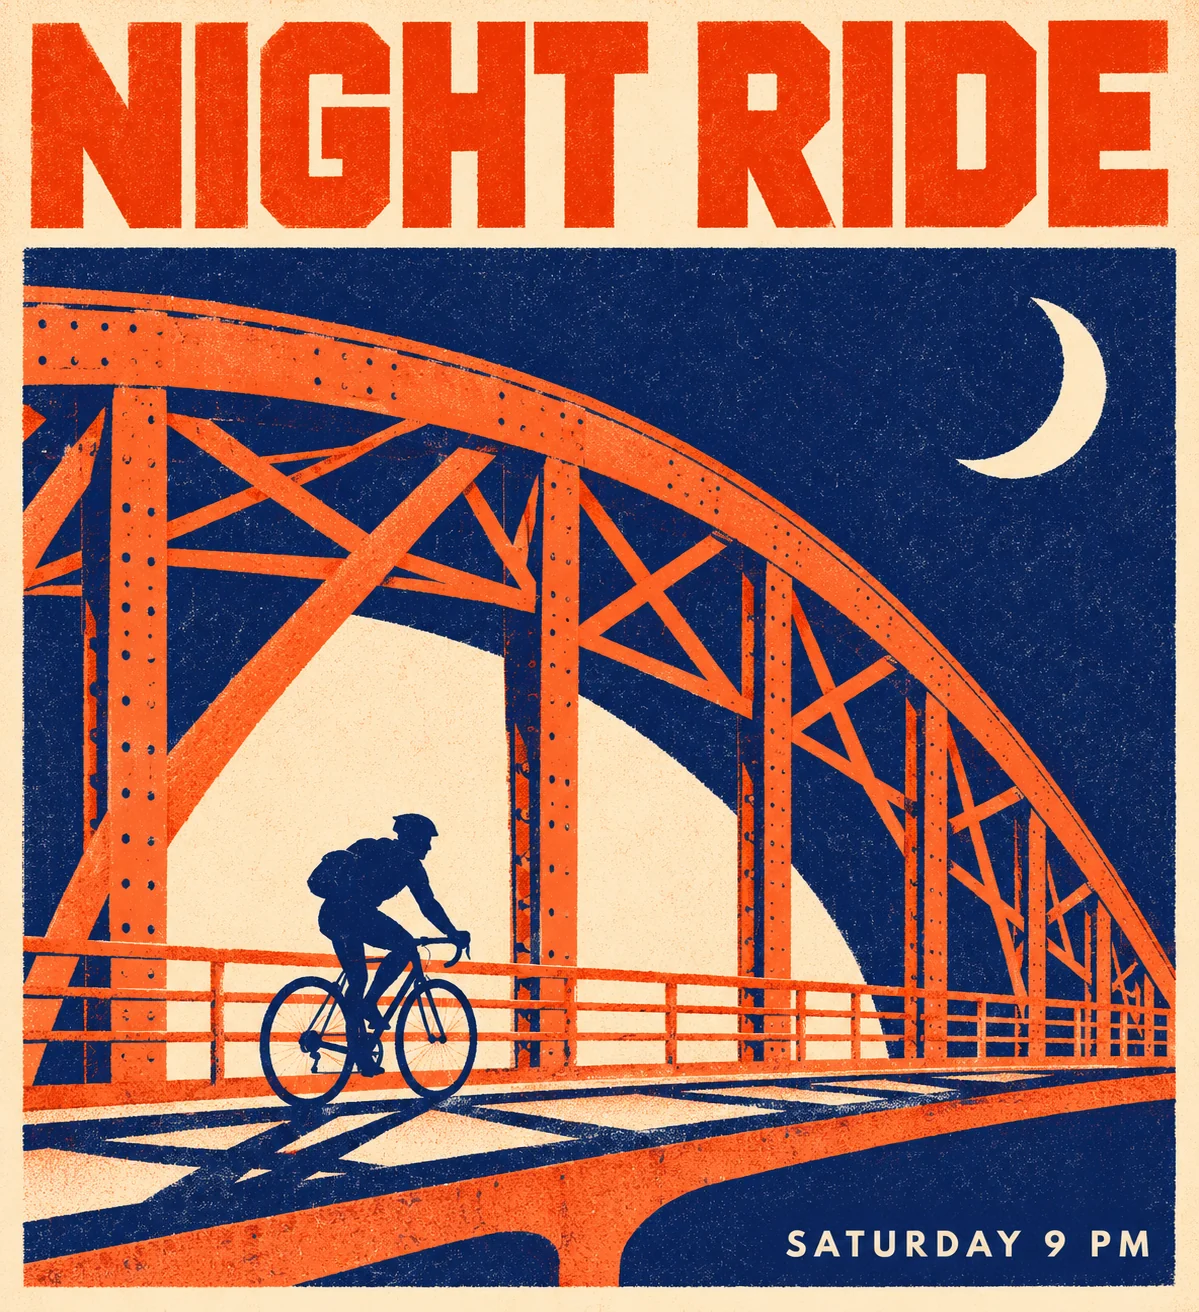
Two-Color Risograph Poster with Quoted Text
A two-color screen-printed risograph poster in vibrant vermilion orange and deep navy blue on warm cream paper showing a lone cyclist riding across an arched steel bridge under a crescent moon. The words "NIGHT RIDE" sit in bold geometric block letters across the top and "SATURDAY 9 PM" in small clean letters at the bottom right, no other text.
Source · MiniMax H3 Community License · 2026-11-03Architecture, Native Resolution Table & Hardware Comparison
33.1B Single-Stream Transformer
Built on the multimodal H3 backbone with 50 layers, 56 attention heads and 3D multimodal RoPE. Text prompts are encoded through a 50-layer Qwen3-VL encoder while uploaded reference frames pass through a 24-channel 2D ViT spatial VAE into one unified sequence.
6-Step & 8-Step CFG-Free Sampling
Distilled with per-step PDD output heads at fixed guidance 1.0. Because classifier-free guidance and negative prompts are eliminated, every request completes in 6 to 8 deterministic steps with natural tonal roll-off, authentic skin pores and crisp typography.
Cloud Browser vs Local VRAM
Self-hosting the full BF16 checkpoint requires 66.28 GB for the diffusion transformer, 66.7 GB for the text encoder, and 2.34 GB for the VAE (~135 GB total on H200/B200 accelerators). Even 4-bit ComfyUI quants require 21 GB of VRAM. Here you run both checkpoints instantly in your browser.